A couple of weeks ago a friend sent me this article from a mutual acquaintance at CCP. It's all about the continuous struggle that the MMO guys have keeping their in-game economies balanced amongst all the real-world trading of items and game currency.
I was particularly interested in the stats near the end - in a crackdown on gold farming they managed to drop CPU utilisation 30% through a 2% drop in players (banned accounts who were violating these terms). To paraphrase that; 2% of the player base [revenues] were creating 30% of the load [costs] and that my friends, is what I call unprofitable usage of a product.
When you read that last sentence it makes perfect sense, however so few of us on the web think this way. How often have you looked up your top workload creators (page impressions, transactions) and your top revenue creators (purchasers, subscribers) and compared the two? How sure are you that your costliest customers - that you are probably supporting a collection of CPUs to service - are not marginal or worse in terms of value to your organisation? With sites more data rich than ever (read: more back end work per view) and screen-scraping a more widespread way to acquire content it's worth working to discourage this behaviour or at least make conscious decisions to allow it.
This thinking should be taken all the way back to product design - on the web we tend to emphasise users/visitor/subscribers without really thinking through what constitutes profitable usage.
It's not just about nailing people who are out to exploit you either - as a long time data provider my biggest issues have usually been well-meaning customers with lazy integrations. If you're going to build a client on top of a web API it's quick and easy to poll the bejesus out of it round the clock and then react to data in the responses rather than, for example, get a schedule of 'interesting' data and dynamically set up threads pick up smaller changes to discreet items on separate and appropriate timers. Take trades for example; why hammer a Hang Seng Index Options feed after 4:15pm? Or how about our feed - do you need 5 prices a second for this weekend's football fixtures on Tuesday or would hourly pre-match odds and squad changes be more than sufficient that far out? A slightly trickier initial integration but a better and cheaper product (for both parties) thereafter.
And finally I've always found it more effective to encourage good behaviour than discourage bad behaviour. Sometimes this can be as simple as an SLA which guarantees a superb latency up to a certain number of requests and creeps out in bands beyond that. Other times this can be purely commercial - why not extend better pricing to customers who genuinely cost you less to service or a tiered revenue share to those who contribute more to the partnership?
Showing posts with label performance. Show all posts
Showing posts with label performance. Show all posts
Friday, 26 March 2010


Saturday, 21 February 2009
Scalability is not just a technical problem
There is so much content out there about how to scale out web sites, platforms, and databases – but it all focuses on the production system architecture. Do a Google search for scalability – go on, I’ll wait for you... See what I mean?
Now I know that’s the fun bit to talk about, but being practical for a minute, if you’re starting to scale out systems using techniques like Digg, Flickr, Xbox Live, or the usual suspects like Amazon, Google, and eBay, then chances are that you’ve got a whole lot more scalability challenges than just the product.
If you’re dealing with at least hundreds of thousands of daily actives, then we can probably deduce a bunch of other stuff about your circumstances. We can guess that you’re after reasonably frequent feature drops, have a significant amount of horizontal distribution, a healthy sized engineering organisation, and a strong bias towards availability. And if even half of that stuff is true, then what are the other scalability challenges will you be up against?
How about multiple concurrent projects? If your estate is divided into more than one product then you will more than likely be working on more than one new feature in parallel. This gives rise to all sorts of version control and regression test problems, which demand process and infrastructure quite different to a single effort.
What about disparate teams? You might have people in a number of locations branching, or depending on, the same codebase. That’s a communication barrier which can be tough to solve. Large enough organisations also tend to sprout specialist disciplines, such as user experience and IA – this changes the nature of how teams engage and how work is specified, estimated, and delivered.
And how do you manage environments, tools, and documentation? A complex production architecture begets a complex development infrastructure, as there is a lot more interoperability to test for. Don't forget that with more teams working concurrently, managing contention for these expensive environments also becomes a tricky balancing act. As your products increase in popularity (a good proxy for profitability on the web) NFRs like performance and capacity will become more important and will require specialised tools to measure.
I’d like to see us sharing a little more about our experiences with this side of highly scalable systems – it might not be as sexy as memcached, CAP, and Gossip, but the reality is it is just as important a part of the solution nonetheless.
Tuesday, 2 December 2008
Speed is in the Eye of the Beholder
Yesterday I was coming through Heathrow again, and while I was waiting for my luggage to surprise me by actually turning up, I was ruminating on performance, user experience, and the iris scanner (old BBC link). For those who haven't had the pleasure, we're talking about a biometric border security system based on the unique patterns in an individual's eye, implemented at certain UK borders as an optional alternative to traverse passport security in a self-service way.
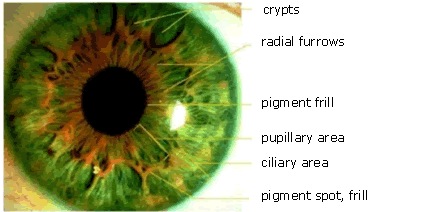
Flying internationally at least once a month for the last couple of years, I've been a regular user of the iris scanner since it's early trials. Like all new technology, it went through a period of unreliability and rapid change in its early days, but its been pretty good for a while now. Step into booth. Have picture of eyes taken. Enter the UK. Awesome.
The only problem is that...
It...
Is...
Just...
Too...
Slow...
Don't get me wrong - you don't have to queue up for it (yet) and you do spend less time overall at the border - it's just that, for a high tech biometric solution, it seems to take an awful long time to look me up once it snaps what it considers to be a usable image of my retinas. You know, in real time it isn't even that expensive - probably an average of about 5 or 6 seconds - but it's just long enough for you to want to keep moving, hesitate, grumble to yourself, briefly wonder if it's broken, and then the gates open up.
It occurred to me that maybe my expectations as a user were perhaps unfair, but then quick as a flash I realized - hey, I'm the user here, so don't I set the standard?
So that's when I started to think about how the performance of this system could be improved, and caught myself falling straight into rookie trap number 1:
I started making assumptions about the implementation and thinking about what solutions could be put in place. I figured there must be some processing time incurred when the retinal image is captured as the machine picks out the patterns in my eyes. That's a local CPU power constraint. Once my retinal patterns are converted into a machine-readable representation, there must be some kind of DB lookup to find a match. Once I've been uniquely identified, I imagine there will be some other data sources to be consulted - checking against the various lists we use to keep terrorists and whatnot at bay.
Well this all sounds very read intensive, so it's a good case for having lots of local replicas (the iris machines are spread out over a number of terminals). Each unique 'eye print' is rarely going to come through more often than days or weeks apart, so most forms of request caching won't help us much with that. Of course there is also write load - we've got to keep track of who crossed the border when and what the result was - but we can delay those without much penalty, as it is the reads that keep us standing in that booth. Maybe we could even periodically import our border security lists to a local service if we observe a significant network cost in checking against them for each individual scanned through the gate (assuming they are currently maintained remotely by other agencies).
Ignoring the fact that I'm making all sorts of horrible guesses about how this system currently works, these seem like reasonably sensible patterns to me, so what's the rookie trap?
Simply that I didn't start by understanding the basic problem I am trying to solve, instead rolling up my sleeves and diving straight into the technical complexities. In doing so, I might have overlooked a plain, simple solution and that's usually bad - why solve a problem in a complex, expensive way when a simple, cheap way will do just as well?
In this example, the problem is not that 5 seconds is an unacceptable time to process the image, compare the data against the registered users, and then pass all the additional border security checks - the problem is that 5 seconds feels like a long time when you're standing in a glass box waiting for it all to happen!
So what else might we have done instead of a major re-architecture of the iris back end? How about just lengthening the booth to form slightly more of a corridor, with the scanner at one end and the gates at the other? With this simple trick, it still takes 5 seconds before the gates can open, but it doesn't feel like it - you haven't been standing still waiting, there is a sensation of progress.
Same level of system performance, very different user experience.
General engineering lesson 1 - customer experience is king. Monitoring and other data driven metrics are important, but how it really looks and feels to your users matters way more than whatever you can prove with data. They'll judge you by their own experiences of your system, not by your reports.
General engineering lesson 2 - you don't have to solve every problem. Sometimes it's better/cheaper/faster to neutralize or work around the issue instead. You might not be able to build a different floor layout, but you can do things like transfer data in the background (not locking out the UI) and show progress 'holding' pages during long searches etc.
Oh and just for the record, I really have no idea how the back end of the iris system works - you are supposed to be seeing the analogy here...
Subscribe to:
Posts (Atom)