Showing posts with label architecture. Show all posts

Saturday, 17 August 2013

The business value of technology

There's already plenty of material on articulating the value of technology in a business sense, but it tends to be quite - I don't know - corporate I guess, and most focus on the justification of a particular framework or product.  That might be quite appropriate in an IT environment, but less helpful in more visceral engineering endeavors.

So what's the justification for good method, design, and computer science?  How do you map that academia to real business concerns?  A while back I made a handy reference guide for my business buddies:


I don't believe that's comprehensive, but I do believe it's prototypical.

Saturday, 3 December 2011

Eachan's 5 Laws of Platform Architecture

Architecture - the shape of the system, the patterns used - is by far the most meaningful thing to get right in any system.  Architectural decisions have far more influence on the capabilities and limitations of any given system than the implementation decisions - frameworks and languages - ever can.

This effect is hugely magnified when you're building a platform, because you're creating tools and raw materials for other developers, and your decisions can enable them to easily build apps any way they can imagine or limit their options to a handful of pre-configured choices.

Side note here; the internet is becoming full of platforms.  It has never been easier to programmatically consume services on the web, even through interfaces originally only intended for humans, and combine existing data in new ways to create whole new experiences.  You might put an app out there for customers, which you consider to be a finished product, and then discover that someone else is using your app as a building block in their app.  One man's front end becomes another man's back end.  I think this is a good thing for momentum and creativity; allowing new takes on current ideas to be spun up and explored quickly and cheaply.

But if you intend to build a platform, if that's what you're explicitly setting out to do, then there are some design guidelines which will lend it greater commercial utility.  Not patterns per se, more like principles, which I'm going to call the 5 laws of platform architecture:

1st Law of Platform Architecture - the value of a platform is directly proportionate to the amount of work it causes to be unnecessary.

Most web businesses are more similar than they are different.  There is a set of web basics they all need (identity, profile, cart, payment, analytics...) and there are usually a set of line-of-business basics that most of them have in common (in my case that's things like inventory, price, geography, booking, weather...) and that's an awful lot of code that we're all writing.  If a platform solves the 'common problems' via a handful of simple web service calls, then partners using said platform can put the majority of their time and passion and investment where it will make the biggest difference to their business; building the unique features which distinguish them from the rest of the marketplace.  I like to ask "what don't my partners have to do because we already did it?" and I like to have a long list of things to put into that bucket.

2nd Law of Platform Architecture - ease of adoption maps directly to business momentum.

Most serious platforms are monetised in the same handful of ways, and in most cases the sooner you can have partners up and running the sooner you're counting revenue from them, ergo time to market for your partners is a lever in your own P&L and if you focus on ease of adoption you will bring on more partners, they will each 'go live' quicker, and it is cheaper than more traditional incentives such as offering improved commercial terms in exchange for faster rollouts etc.  The kinds of things you ought to consider here go beyond the simplicity of the services you expose (which must be easy for the most pedestrian of developers to grok - in the platform game you are penalised for externally-observable complexity) and into how much you invest in documentation, SDK and client code, and developer community support.  These things pay you back.

3rd Law of Platform Architecture - entrypoint depth multiplies the business flexibility of any given service.

Higher layer abstractions always infer business logic.  That's what a composite service really is; someone decided that for use case alpha, you always do X then Y then Z, and therefore aggregating calls out to services A and B and C solves that problem in a single call.  You have just created a simpler solution for alpha - which is an admirable achievement and it belongs in your platform exposed to everyone else who has use case alpha.  But let's say I have use case alpha prime?  A basically similar business process but with key differences that no longer require data from B?  That's why your underlying services belong in your platform too; if a client has some business logic which maps quite closely to the higher layer abstractions then that's great orchestration for that app.  If a partner want to do something a little different, then he might have to consume those composites and do a bunch of his own transformations on the data, perhaps even store the data himself, and then present it to the client apps through his own interfaces.  With the option of consuming services from lower down the stack clients can build unique apps on top of the platform with far less 'back end' work (stripping out the inferred but irrelevant business logic) on the client side.

4th Law of Platform Architecture - compute work becomes exponentially cheaper and faster as it approaches the edge.

At last something more technical!  If you're building a platform, and you're not planning on comprehensive global coverage, then I would question your commitment to your idea on a web where ubiquitousness has never been cheaper to claim.  So let's assume that you are doing this globally.  Without getting into a discourse on distributed systems, you're going to want to deliver straightforward and performant access to every consumer regardless of where they're based.  That is a distributed system problem, and so your platform should run on a system with a diameter greater than 1, and you should try to service requests as close to the edge (and as high up in your stack) as you can.  There are plenty of mature grid and edge computing infrastructures out there to provide the scaffolding for this.  What does it mean for your partners?  They're using a platform with better durability and lower latency than alternatives that they might choose, which translates into better SLAs and better service which also happens to be cheaper to deliver.

5th Law of Platform Architecture - as services become more atomic the addressable market segments become more broad.

My 3rd law deals with entrypoints, and this is nearly the same thing.  Lower layer abstractions allow platform consumption without constraining the use cases, but another critical property of those granular services is their atomicity.  Your low level granular services must perform generic, stateless (independent) operations, all be individually consumable, and each should be of business value individually.  When I say individually consumable I think I really mean individually usable.  If one has to consume a handful of other services to be able to make sense of the data returned from a single service, then it clearly isn't too useful in it's own right.  Perhaps it needs slightly more data or metadata around it or maybe it is just noise in your stack - keeping the catalogue manageable is actually a harder problem than it may seem.  When your lower layer abstractions are individually useful you find that more kinds of businesses can make use of them.  To round this out with an example; exposing our geography data distinctly (i.e. outside of a composite which applies it to a booking flow) enables us to power navigation and mapping apps, instead of just travel apps.

These are guidelines for architecting a platform to maximise its utility to developers and its commercial success as a set of business building blocks for a range markets.  But what about the shape of the system(s) behind each service?  That dimension of architecture - how you manifest each of your APIs - is just as important.

We all have our favourite ways of doing things, and pushing one pattern over another without an understanding of the business problem and environment is just bad science, so the best I can do here is suggest establishing some engineering principles to give engineers a decision making framework within which they can own the problem and still consistently meet the higher standards expected from platforms.  Scalability, Maintainability, Quality, Security, Availability, and User Experience have always worked for me.

Whatever you do keep in mind that if you operate a platform, then you're partly responsible for the availability and integrity and brand and revenue of n number of businesses (i.e. the partners building their apps on your stuff) so you have an even greater responsibility for quality than you do when your building your own customer-facing apps.  I'm a pretty casual guy about most things, but that's a responsibility I take very seriously indeed...

Saturday, 5 November 2011

The difference between taking a shortcut and cutting a corner

There are two very different things to talk about here, with two very different implications for your software, but I'll admit that which way around you label them can simply be language pedantry.  So for the purposes of this discourse, let's say that:
  • Taking a shortcut is using your knowledge and experience in place of studying things from first principles every time.
  • Cutting a corner is a compromise in quality or good practices in the place of the prudent actions otherwise required.
Both are used to speed progress through a given piece of work.  Using knowledge and experience is a time to market competitive advantage gained through having talented people, compromising quality is a time to market advantage gained through process; albeit purchased at the price of later cost.

Taking Shortcuts

Let's talk about taking shortcuts first.  When you can do this confidently it is a magical place to be.  I like to hire really smart people and give them the freedom to use the experience they've gained throughout their careers to leap frog us straight over the other organisations who had to do it all from scratch, the sources of the experience I want to tap into.

Experienced people have been through years of doing everything by careful analysis and research, gradually proving out a larger and larger set of assumptions which they can build up from, and using life's great feedback loops to tune their thinking until their instinctive decisions are as a good as a noobie's 3 months of science.  That's why we hire the kind of people we hire.

Having all that collective wisdom at hand and not using it is irresponsible leadership and suffocating to the innovators you should be growing.  There are still times when the right thing to do is take things back to first principles and do that 3 months of science, but the beauty of experience is it also tells you when it's right to use your instincts and when it's right to figure it out.

Cutting Corners

And now cutting corners.  Reducing time to market but doing something less well (sacrificing quality) or by skipping validation steps such as doing less testing (taking more risk) works in the sort term, but really just exchanges a short term temporal win for a lot more trouble later.  Often more later trouble than you really think, which is why this accelerent is so frequently misused.

I say 'freqently misused' quite deliberately, because in a pragmatic real world it is not always the wrong thing to do.  Occasionally it can even be the path to very big wins, when time is absolutely of the essence and every day counts materially.  But it is always the wrong thing to do to unconsciously blunder into cutting corners, to not be actively managing your quality, and to incur this type of technical debt without having a credible plan to come back to fix it up before it festers too long.

If you are not grown up enough to manage the payback, then you are not grown up enough to incur the debt.

So...

Hire people smarter than you are.  Empower them to use what they know and what they've done for your benefit - that's what they want anyway - and to use their time with you to further expand their horizons.  Carefully manage your quality, incur technical debt strategically, and never do it without paying it back.

You'll do a good job and everyone will have a good time, most importantly your consumers.

Tuesday, 31 August 2010

The Abstraction Trap

Abstractions exist so that we can take shortcuts when building stuff.  They readily implement some of the messy necessities behind things like, for example, network access in distributed systems – but too often they’re used as an alternative to in-depth understanding rather than a reusable way to render a system.

Staying with our distributed system example; understanding the latency between nodes, synchronisation and blocking (and their impact on concurrent work), transport overhead and reliability, and what the behaviour will be if you don’t hear back from the remote service are all critical to the success of a complex project.  Without having to explicitly program these things it’s too easy to just drop something into a pipe or throw it at a web service and merrily continue on with life having never even considered those neatly masked complexities.  Until go live.

It’s the difference between something that functions on the bench and something that will work reliably in real life’s volatile conditions.

On the infrastructure side I see the same pattern emerging with virtualisation – we’ve now got this nifty and easy to use platform which takes us another step further away from the metal.  On the plus side we can stamp out more nodes really quickly and move instances of a server around from hardware to hardware to accommodate growth and failure, but on the minus side correlating what’s happening on pretend CPUs with a real CPU and oversubscribing hosts makes capacity planning a degree harder.

All these environments are designed to abstract things away from us so that we don’t have to worry about them or recreate them every time – but that’s not the same as saying we no longer need to understand the basics of what happens under the hood.

You’ll always have better product when your engineers have the low level knowledge (primitives and patterns) needed to design and build systems and understand how they will behave.  That’s different to simply knowing how to drive the tools.

Tuesday, 27 July 2010

Architecture in Agile

When a team first starts practicing agile a question that usually comes up fairly early is where architects fit in.  In a set of processes which usually considers ‘big-up-front requirements’ it’s nemesis, it can be a startling realisation that we (the engineering side) might have our own version of that.  Architecture tends to be associated with big-up-front specs and, if you’re not doing any of that big-up-front stuff, then where does the role of an architect fit in?

The first step towards finding your answer to that question is to understand what architecture actually is:

Architecture isn’t something separate and distinct from your projects that you can either choose to indulge in or choose to abstain from – architecture is simply the shape of what you produce.  Everything piece of software in the world has architecture, the only question is whether it was done by design or by accident.  The question is essentially whether you drive it explicitly and control your technical destiny or whether you leave it to chance and hope for the best.  Driving it would be the job of the architect.

To make a slightly controversial statement, architecture by itself has no value.  But architecture, as defined as ‘the correct technology platform meeting the current and future functional and non-functional needs of the business’ is worth everything that you can put into it.  I believe in architecture.

Architecture must be explicitly handled – lest it get away from you and leave you with unsustainable systems – but that’s not the same as saying that you must have an architect.  You simply need to have the responsibility for the shape of the system (the technical decisions) clearly understood.  Why not devolve the responsibility?  Something common to most agile approaches is the empowerment of the teams to self-organise and take control of the destiny of their own product.  Architecture is no different and, where you can identify neat boundaries between different products owned by different teams, this type of ‘product architecture’ works very well with minimal enterprise oversight.  Less distinct separation between systems generally = more enterprise oversight.

Somewhat counter to the freshman agilist’s intuition, you do need to make some up-front decisions in most projects.  Agile is about making sure you know enough about something to be effective by when you need to know it – it’s not about knowing nothing.  The trick to handling technical designs is knowing what those up-front decisions should be and what’s better handled as part of how the project evolves.  Unfortunately this judgement takes some experience to develop, but a good guideline is to stick to things which can’t be easily changed later – such as schemas, APIs, and namespace.

If you’re a formally nominated architect in an agile environment my advice is stick to patterns and delegate implementation decisions.  When you are dealing with a flow of work and you can’t initially nail down the complete set of requirements in buildable detail – the business case for agile – then you have to let your vision for the product, and the size and nature of the commercial opportunity it supports, help you pick out the right patterns.  Patterns are the best currency for an architect to deal in if he has a team of smart developers keen to take some ownership; the ‘here is a design doc, build this’ approach becomes a constraint rather than a support.

In more larger or more complex agile environments – with multiple development teams and multiple products – an architects role moves into governance; the design of common elements and the way in which products integrate and interact.  What we might call enterprise architecture I guess.  The goal here is to put together a framework which promotes self-contained and distinct products, giving each team their own jurisdiction while still ensuring smooth overall performance of the whole estate.  In my experience this maxes out the total delivery throughput of the whole organisation and gives the satisfaction of ownership to the doers.

If you’re new to architecture (giving or receiving!) and need to make sense of all this then I’d recommend joining IASA because a key part of our mission there is bringing clarity to what an architect really does for a team, a product, and a business.

Thursday, 29 April 2010

Technical Debt Credit Rating

A while back I wrote about how closely technical debt paralleled financial debt and then a short follow-up post with the meta-message that, through the right reductionism, certain things will always cost you an inescapable minimum and the decision that you really have is about where you choose to make that payment (I argued that you either pay through the correct design and build initially, or you pay through unnecessarily increased maintenance costs later).

Outlawing technical debt is as foolhardy as always cutting corners - sometimes the right thing to do is to take a hit to get something out sooner or in a certain shape - the problem is in the repayments; in other words, they often don't exist. And if you don't go back and sort your hacks out early they tend to accumulate in the system and before you know it developing on it is like moving through treacle (and the treacle occasionally catches fire). Everything else you do takes that much longer and is that much more expensive (and those are business metrics) and can have unintended consequences - it's a crippling burden just like its financial counterpart.

I have a rule - no one is allowed to take technical shortcuts through a project [where that = incur some technical debt] without showing where, in the same plan, they go back to do some refactoring so that our long-term assets remain sustainable. We're pretty lucky at Sporting Index; most of our stakeholders value technology and recognize how critical it is to the business, so it's a conversation I rarely have to have - but I know many other companies are less fortunate.

So now I think I have a better idea. It came to me while I was thinking about why, if technical debt is so similar to real debt, it doesn't regulate itself in the same way - and I think that's becuase there is no concept of creditworthiness in technical debt, in other words no assessment of a team's ability to 'repay' a quality compromise (read: loan of functionality to the business ahead of when it otherwise would have been ready) alongside all the other outstanding quality compromises that they already have.

But we might be able to simulate that...

Imagine giving each product manager a 'credit rating' of, say, 3 - meaning they could call for unsustainable technical shortcuts 3 times as they worked with the delivery team to determine their solutions. Once those 3 debt points were used, that product manager would be unable to encourage the team to make further quality compromises until at least one of those was paid back. If you have product managers with a demonstrated track record of revisiting earlier deliveries to address technical debt then why not give them 5? A higher creditworthiness ought to enable an individual to take on more concurrent debt as we can be more confident that they'll come back to service it.

I pretty much guranttee that any product manager's cavalier attitude towards shortcuts would change and they'd suddenly treat technical debt as the instrument it really is and use it only where it mattered materially. That, ladies and gentlemen, is a feedback loop.

The downside is that you'd have to be better at tracking this sort of thing and, like any other method, it'll need some discipline when a product manager with maxed out technical debt points wants just one more shortcut. If you've ever had to maintain a spaghetti codebase (as most of us have at some point) then you'll know that these things need closely policed anyway, so perhaps being forced into formally tracking it isn't so bad.

Wednesday, 28 April 2010

Nobody Wants Computers

Well they shouldn't - they should want what computers will do for them.

Many people turn up to conferences or SIG meetings and ask me how virtualisation or a centralised inventory database or VPNs (or pick something) will help their company. Misguided. My response is always the same - what is your business case and what benefits are you expecting? I do get quite upset when I don't get a good answer to that, because it means someone somewhere is cooking up some technology for technology's sake.

Sales functions are excellent at creating a need around a product they sell - great if you're in that business and I used to be - but it is the functionality your organization really needs that should matter. Talk to me about outcomes, goals, what you want to be able to do from a business capability perspective, and then the right technical solution will fall out of that.

Contorting business processes to fit a specific technology or vice versa - i.e. doing it backwards - only ever works when combined with a healthy dose of luck.

Wednesday, 17 March 2010

Cloud Congress Done Quick

[well, my bit at least]

Yesterday I spoke at this year’s Cloud Computing Conference covering what cloud computing really is all about (once you peel away the hype) and how to break the back of the adoption problem – what do you put out there and how do you get started? It was the first time I’d ever done a talk that had absolutely no diagrams or pictures whatsoever in the presentation and, considering the plainness of the slide deck, it didn’t go too badly at all.

Excluding the mundane introduction, here’s the reader’s digest version of my key points:

What's in a cloud?

As a relativity new and trendy technology cloud computing is open to a lot of debate and even the 'correct' interpretation changes as the technology matures. We've had web applications for a long time now, so I'm not comfortable with SaaS being thrown into the cloud bucket. I like to define it in the context of how it changes how you deliver software (by abstracting away the complexities, layout, and connectivity of infrastructure from you developers) and how it impacts the way delivery costs are calculated (by exchanging metered billing on a usage basis for CAPEX-heavy up front acquisition).

My test (does your definition of cloud computing rely on the observations of your end users?) is simply to ask yourself "am I saying I am a cloud company just because my users access my product over the web?" If so, then perhaps you need to consider that maybe you might not be. Nothing wrong with that, but nothing new either.

What your FD sees

My next section expanded on the CAPEX vs OPEX shift that cloud platforms enable. If you have got your product design right then - on the web anyway - more usage should equate to more revenue and, with a cloud platform, more usage equates to more cost. See how that works? The cost base grows in line with revenues, therefore smoothing out that lumpy accounting and tricky budgeting activity that is characteristic of large hardware drops throughout a site's lifetime. You've also able to bring new things online relatively quickly (eliminating the ordering/delivery lead time/racking and stacking stages) and you can afford to try out slightly more speculative business cases - if I'm on the fence about a particular feature then I'm much more likely to give it a try if I know I can pack it up quickly and cheaply later if it's turns out for the worst.

Most cloud platforms have pretty good metering systems in place and that allows you a much more granular view of what part of your system is directly responsible for what parts of your cost base. From a business case perspective my advice here is to include all costs and not forget about time as a factor. Sounds a little obvious but when, for example, looking at Amazon's S3 as a storage platform for an analytical data set your total cost is going to include the transferring in and out of data as well as the cost per GB of storing it. Time matters too - I've seen the odd business case for a cloud platform fail to stack up because over a 3 year period more total cash is paid out than total cash spend once the large CAPEX bill is amortized over the same period.

Cloud capabilities

I also touched on some of the less obvious uses for cloud computing because so much emphasis is given to migrating existing systems into the cloud and I don't think enough time is given to considering what additional things that aren't being done now could be brought on because of the inherent properties of cloud platforms. These include private content delivery networks (because the larger cloud players tend to have a good reach), enabling offshore or outsourced development without opening your perimeters to external organizations who may have weaker security policies, neutral territory for integrations or joint ventures, and large scale load testing (because where else will you get hundreds of high spec load generators external to your network and connected over realistically-latent lines).

Development and testing environments are a good way to dip a toe in because, if you're doing it right, you will already have nicely sanitized data (which gets you clear of most of the oft-cited security concerns) and you won't be expecting production-sized load. It's also the best way to get a good feel for the cloud suitability of your production system without making any user impacting changes.

Architecting for the cloud

Many people - mostly those selling cloud integration tools or who charge by the hour - will tell you about how they can help you move your systems into the cloud. Don't kid yourself on. If you're using a half-way decent definition of a cloud platform then there is a lot more to it than is commonly appreciated. There are a number of good design patterns that I believe organizations should start adopting today and not just because they prepare systems for cloud runtime in the future, but also because they're pretty good ideas on their own merits.

It all starts with my favorite - decoupling and creating clear, distinct boundaries between functionality in a system and abstracting the specifics of the implementation which delivers said functionality behind a well defined interface. When you present specific uses of data to a network in this way then, subject to a bunch of common sense rules, you are able to host that individual part of your overall system another way - on different servers, in another data center, or hey, in the cloud! As long as it's reachable by it's consumers - which brings us nicely onto messaging and using state sparingly - you buy yourself the flexibility to move things quite dynamically. A service registry is also highly desirable if you a) have composites made up of many services and b) want to be able to move them and scale up/down dynamically.

All good practices for scalability and availability regardless of your stance on the cloud.

The crystal ball

You're not allowed to speak at an event and not give some predictions. I think there is an old charter or something somewhere. So mine were; barriers are coming down and this will continue with technologies such as private link and private clouds, as with all trendy concepts the waters will be muddy for a while as the word 'cloud' is appended to everything we've already got in order to sell it to us again, and within 5 years I expect to see hybrids (cloud-type platforms in use to some degree) in almost every organization.

Overall a good conference - some top panelists and speakers, and I met some great folks there. Thanks to all the guys and gals at SixDegrees for putting together a worthwhile and fun event.

You can find the slides here.

Wednesday, 6 January 2010

The hidden wisdom of Kevin McCloud

I was lucky enough to get a copy of the Grand Designs Handbook for Christmas - it's a compendium of building projects from the channel 4 show (the book, not Christmas). The first few chapters have a lot of lessons learned and good practices picked up from 9 seasons worth of experience with, well, variously successful building projects.

Reading some of the advice, there is a lot that can be applied directly to software projects. There is a section on 'how to behave with your team' which is aimed at helping people keep their building sites productive - but the advice translates well to technical projects. Here's a couple of my favorites along with my join-the-dots:

"Don't give verbal instructions on site unless they've been agreed with your consultants and they're backed up in writing. If you just issue verbal instructions, you risk confusion and possible extra costs."

This is a top one for me - especially in the agile world where many interpret 'agile' as 'make it up as you go along' and then end up disappointed. I think maximizing interaction between delivery team and customer team is a good thing especially when both sides recognise the boundary between clarification and change in in-flight work.

"Do take time to prepare detailed written briefs setting out all your requirements for all your consultants. A good brief is an essential part of the design process."

One of the simplest formulas the govern all project delivery (hardhat or mousepad) is that the quality of what you get out with never exceed the quality of what you put in - yet this seems to escape so many of us so often. What you invest in clear instruction and regular contact with developers is a key variable in how happy you'll be with the results.

"Do allow your experts the freedom to do their jobs. Stand back from the project and enjoy your role as client; making decisions and hanging around, generally being a good egg and imbuing the world with optimism and excitement."

I don't exactly advocate stakeholders 'standing back' from a project, and I don't think that's what Kevin means either. Don't micromanage your delivery team and, as a customer, be sure to perceive the difference between decisions you should make (and don't let the team wait for those) and decisions the team should make (and let them use their skills and experience to make them).

"Don't listen to other people outside the professional team. You'll only end up getting very confused."

External feedback and extra ideas are good, but remember that an engineer knows his business best and don't fall into the trap of listening to someone else simply because you like their answers better. I consider myself relatively smart but even I'll say all sorts of wacky things when I don't have any skin in the game...

There are a couple of other sections with close analogies to technical projects - how to be a perfect customer and how to put a good brief together - which I think are 2 other critical ingredients to any successful engineering project (construction or software) but they'll keep for another post.

Wednesday, 16 December 2009

Introducing Sporting Index Super Simple Integration

This year we decided to give our B2B customers an early Christmas present - SSI.

Sporting Index (well, really Sporting Solutions, our B2B brand) provides pre-match and in-play pricing and content to fixed odds bookmakers for hundreds of markets across 16 sports with more events from more jurisdictions being added almost every month.

Traditionally we’ve done this by pushing XML documents around over reliable transports and leased lines. This works very well and there is nothing inherently wrong with this solution, but we weren’t happy that customers had to install expensive fixed lines and associated hardware, and our back end is capable of producing multiple-thousands of price changes a minute – well beyond the rate at which some of our customers can consume them.

On top of this, our customers wanted the low latency and reliable updates that come with a push solutions, but also the easy integration and flexible client-side controls that comes with a pull solution.

Well, you asked for it and you’re the customers, so let’s unwrap this bad boy.

Super Simple Integration is essentially a RESTful web services API available over the good-old-fashioned Internet. The feed is as easy to consume as you’d expect from any web API, and we’ve spent a lot of time on the data formats and doing some clever pub-sub tricks in the background – thus all the benefits of the heavyweight XML services but through an integration which is quick and easy to get to grips with.

There’s a lot to this, so let’s just cover two of the most common use cases:

Get Content

Our content products can be used to populate websites with upcoming fixtures and players, and to power pages or widgets showing points, corners, goals etc as they happen in running matches.

Content products are mostly stateless and work on a fairly simple request-response model, which can mean no integration work at all. Well that’s half true – you still need to consume the data from the API – but you don’t necessarily need to build a repository on the customer side or have to match up schemas.

Let’s say that wanted to build a little scoreboard for my site to show my visitors the progress of a live England v New Zealand rugby game;

API content integration

You get the content you want, as often as you want, delivered back in name-value pairs. There are also a couple of methods to call to list out what sports and events are available, so you can pick out what to pull into your scoreboard app.

Pretty basic stuff so far, where it really gets sweet is how we implement real time price streaming.

Get Prices

Our price products can be used to price up sports betting markets, either as a risk advisory tool for human operators or a totally automated pricing service, and cover a wide range of sports in-play with high fidelity price output.

In price products - particularly once fast paced events turn in-play - state and reliable delivery become important, but we’ve enabled our customers to nicely sidestep the costs and technical complexity this usually involves. When your API client registers interest in pricing up an event we build you your very own data object, which we call a channel, and then it works like pub-sub system. Our back end pricing engine is event driven, and as events occur which trigger price changes, those changes are accumulated in the channel you’ve subscribed to and delivered out to your system in real time over secure HTTP;

API price integration

This puts quite granular control of the product into the client-side’s hands, allowing you to programmatically build object(s) with any combination of markets and data that you’re interested in and then subscribe to your very own private feed over familiar transport.

By accumulating interesting data into user-defined objects this way we also buy back the robustness that dedicated WAN links gave us – if there is a network disconnection the client simply re-establishes an HTTP connection to the API and picks up where it left off – no lost updates or re-synching required.

That’s SSI in a nutshell. It’s the easiest integration in the industry, and from our perspective it scales out nicely - being just a collection of smart web services - and also enables us to accelerate the building of data-driven products for our own business too.

Sunday, 27 September 2009

Screen Scraping for Dummies

If you run a website with any sort of valuable content, then you are almost guaranteed to run into scraping sooner or later. Screen Scraping is more or less an automated program taking an impression of a web page and then parsing it to pull out some specific bits of data that the scraper is interested in - which theoretically is then stored or used in some other way.

The piece of software that does this scraping is commonly called a robot, or bot, and it is really just an automated web client that accesses and uses sites in the exact same way as it's fleshy counterparts, just with machine precision and repetitiveness. A bot may be a large and complex program running on a server with it’s own database etc, or as simple as a script running in a browser on a desktop.


This is typically regarded as undesirable behavior by many sites because, in most cases, it’s a source of load and associated with unprofitable usage. Whenever we draw a page impression, which we’ll do for every bot hit just as we do for every human visitor, we consume web server time and, worse, back end time. When we structure highly functional pages loaded dynamic content we can create a very engaging user experience, and all that functionality is built on plenty of back end work and data. When used at regular human pace that's usually OK, but under the relentless rate of hammering robots are capable of, it starts to become expensive.

If you've got a case of bots, you have to start by identifying them. Their repetitiveness and flawless precision is, in this case, their downfall and we can usually spot them easily through proper analysis of web logs - no human user is as mechanically regular, millisecond quick, and consistent in journey as your average droid.

Spotting droids isn’t too hard, but then you've got to decide what you're going to do about it. Most scrapers aren't malicious and often don't realise the headache they're giving you. In the first instance it's best to try some detective work, see if you can find out who they are, and get in touch. Domain registrars can be a great resource for this, but don't overlook the obvious - maybe they even have an account with you if data they're using requires signup to view.

Beyond that it gets tricky, and can easily turn into an IP address blocking arms race. With some caching finesse or smart layer 7 rules you can throttle bot activity to more palatable levels, or persist them to their very own node that they can thrash all day without impacting the experience for the rest of your users.


If robots are a very big problem for you, then try and take it as a compliment on the value of your data and perhaps consider publishing it via a productised API or feed - if you make it simple enough to consume, then most scrapers will willingly change over to a more reliable integration mechanism and perhaps even pay you for it.

Sunday, 14 June 2009

Right First Time

Imagine if the first wall you ever built had to form an integral part of your dream home, or if the first time you ever drew a picture it had to hang in the Louvre? Or if the first cake you ever baked had to be for your daughters wedding?

That’s clearly unreasonable.

So why does it seem reasonable that the first iteration of a new system you build should be the one that your business depends upon?

That’s why we prototype. That’s why we iterate. That’s why we beta. Don’t rob yourself, and your organisation, of the wisdom you’re owed from those lessons.

Tuesday, 10 March 2009

Don't out-specify your knowledge

Combining some points from this post by Joe Armstrong and this post by Dan Creswell gives rise to some interesting implementation thoughts.

Standardisation is important, particularly in the context that Armstrong frames it in - if the interaction between a client and a server closely adheres to a predetermined protocol, then the systems overall behaviour becomes more predictable and easier to adapt and fault find.

But then this depends on the maturity of your understanding of your problem and your solution. As Creswell says at the beginning of his post, defining too much up front can be a trap. Coming up with a set of standards that are too rigid too early might start you down a road of building that system instead of building the right system.

Standards, patterns, and contracts are all important - but timing is key.

Friday, 16 January 2009

No Pain No Gain?

For the past couple of days I've been helping out a friend get a new team organized, and during our of discussions in their canteen, I overheard something that epitomizes the complexity-aholics that really drive me mental.

A couple of data architects were talking about a consolidation project they were kicking off. "Can you believe what they're doing in the Japanese office? Their schema is so basic" one complained to the other. "Yeah, they clearly don't know what they're doing" his colleague replied, "they should leave it up to us." A couple more minutes of the same and I couldn't really let it go.

Deep breath...

Gathering up my most diplomatic tone, I asked the resident geniuses: "OK lads, if you're saying that they have a basic, simple solution which meets the business requirements, and you have a complex, difficult solution which meets the business requirements - then isn't it you who have something to learn from them?"

You see this is why I don't have any friends.

But seriously, what's the attraction to building big, creaky, behemoth solutions where something easy and elegant would meet everybody's expectations? Why is it that we seem to derive satisfaction from making our lives hard? Unless you're very lucky (lazy?), you'll have to troubleshoot, maintain, and support whatever you put in place.

I've noticed before that good engineers can build vast systems with webs of dependencies and many moving parts, but it's the great engineers who realize that this is a bad idea.

Outside of the gym, there are very few places in the world where you'll be better rewarded for increasing the effort necessary to achieve a given outcome.

Saturday, 13 December 2008

Failure Modes

Whenever we're building a product, we've got to keep in mind what might go wrong, rather than just catering mindlessly to the functional spec. That's because specifications are largely written for a parallel universe where everything goes as planned and nothing ever breaks; while we must write software that runs right here in this universe, with all it's unpredictability, unintended consequences, and poorly behaved users.

Oh and as I've said in the past, if you have a business owner that actually specs for failure modes, kiss them passionately now and never let them go. But for the rest of us, maybe it would help us keep failure modes in the forefront of our minds as we worked if we came up with some simplified categories to keep track of. How about internal, external, and human?

Internal
I'm not going to say too much about internal failure modes, because they are both the most commonly considered types and they have the most existing solutions out there.

You could sum up internal failures by imagining your code operating autonomously in a closed environment. What might go wrong? You are essentially catering for quality here, and we have all sorts of test environments and unit tests to combat defects we might accidentally introduce through our own artifacts.

External
The key difference between external and internal failure modes is precisely what I said above - you are imagining that your code is operating in perfect isolation. If you are reading this, then I sincerely hope you rolled your eyes at that thought.

Let's assume that integration is part of internal, and we only start talking external forces when our product is out there running online. What might go wrong?

Occasionally I meet teams that are pretty good detecting and reacting to external failures and it pleases me greatly. Let's consider some examples; what if an external price list that your system refers to goes down? How about if a service intended to validate addresses becomes a black hole? What if you lose your entire internet connection?

Those examples are all about blackouts - total and obvious removal of service - so things are conspicuous by their absence. For bonus points, how are you at spotting brownouts? That's when things are 'up' but still broken in a very critical way, and the results can sometimes cost you far more than a blackout, as they can go undetected for a while...

Easy example - you subscribe to a feed for up-to-the-minute foreign exchange rates. For performance reasons, you probably store the most recent values for each currency you use in a cache or database, and read it from there per transaction. What happens if you stop receiving the feed? You could keep transacting for a very long time before you notice, and you will have either disadvantaged yourself or your customers by using out of date rates - neither of which is desirable.

Perhaps the feed didn't even stop. Perhaps the schema changed, in which case you'd still see a regular drop of data if you were monitoring the consuming interface, but you'd have unusable data - or worse - be inserting the wrong values against each currency.

Human
Human failure modes are the least catered for in our profession, regardless of the fact they're just as inevitable and just as expensive. You could argue that 'human' is just another type of external failure, but I consider it fundamentally different due to one simple word - "oops".

To err is human and all that junk. We do stuff like set parameters incorrectly, turn off the wrong server, pull out the wrong disk, plug in the wrong cable, ignore system requirements etc - all with the best of intentions.

So what would happen if, say, a live application server is misconfigured to use a development database and then you unknowingly unleash real users upon it? You could spend a very long time troubleshooting it, or worse still it might actually work - and thinking about brownouts - how long will it be before you noticed? For users who'd attached to that node, where will all their changes be, and how will you merge that back into the 'real' live data?

Humans can also accidentally not do things which have consequences for our system too. Consider our feed example - perhaps we just forgot to renew the subscription, and so we're getting stale or no data even though the system has done everything it was designed to do. Hang on, who was in charge of updating those SSL certificates?

Perhaps we don't think about maintenance mistakes up front because whenever we build something, we always picture ourselves performing the operational tasks. And to us, the steps are obvious and we're performing them, in a simplified world in our heads, without any other distractions competing for our attention. Again - not real life.

And so...
All of these things can be monitored, tested for, and caught. In our forex example, you might check the age of the data every time you read the exchange rate value in preparation for a transaction, and fail it if it exceeds a certain threshold (or just watch the age in a separate process).

In our live server with test data example, you might mandate that systems and data sources state what mode they're in (test, live, demo, etc) in their connection string - better yet generate an alert if there is a state mismatch in the stack (or segment your network so communication is not possible).

The question isn't are there solutions; the question is how far is far enough?

As long as you think about failure modes in whatever way works for you, and make a pragmatic judgement on each risk using likelihood and impact to determine how many monitors and fail-safes it's worth building in, then you'll have done your job significantly better than the vast majority of engineers out there - and your customers will thank you for it with their business.

Tuesday, 2 December 2008

Speed is in the Eye of the Beholder

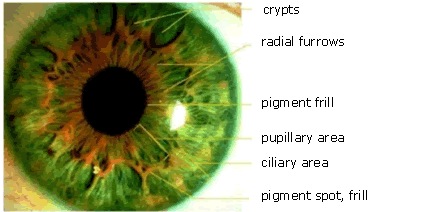
Yesterday I was coming through Heathrow again, and while I was waiting for my luggage to surprise me by actually turning up, I was ruminating on performance, user experience, and the iris scanner (old BBC link). For those who haven't had the pleasure, we're talking about a biometric border security system based on the unique patterns in an individual's eye, implemented at certain UK borders as an optional alternative to traverse passport security in a self-service way.

2B5E815C-63E0-4921-B5B4-C3F979924E23.jpg

Flying internationally at least once a month for the last couple of years, I've been a regular user of the iris scanner since it's early trials. Like all new technology, it went through a period of unreliability and rapid change in its early days, but its been pretty good for a while now. Step into booth. Have picture of eyes taken. Enter the UK. Awesome.

The only problem is that...
It...
Is...
Just...
Too...
Slow...

Don't get me wrong - you don't have to queue up for it (yet) and you do spend less time overall at the border - it's just that, for a high tech biometric solution, it seems to take an awful long time to look me up once it snaps what it considers to be a usable image of my retinas. You know, in real time it isn't even that expensive - probably an average of about 5 or 6 seconds - but it's just long enough for you to want to keep moving, hesitate, grumble to yourself, briefly wonder if it's broken, and then the gates open up.

It occurred to me that maybe my expectations as a user were perhaps unfair, but then quick as a flash I realized - hey, I'm the user here, so don't I set the standard?

So that's when I started to think about how the performance of this system could be improved, and caught myself falling straight into rookie trap number 1:

I started making assumptions about the implementation and thinking about what solutions could be put in place. I figured there must be some processing time incurred when the retinal image is captured as the machine picks out the patterns in my eyes. That's a local CPU power constraint. Once my retinal patterns are converted into a machine-readable representation, there must be some kind of DB lookup to find a match. Once I've been uniquely identified, I imagine there will be some other data sources to be consulted - checking against the various lists we use to keep terrorists and whatnot at bay.

Well this all sounds very read intensive, so it's a good case for having lots of local replicas (the iris machines are spread out over a number of terminals). Each unique 'eye print' is rarely going to come through more often than days or weeks apart, so most forms of request caching won't help us much with that. Of course there is also write load - we've got to keep track of who crossed the border when and what the result was - but we can delay those without much penalty, as it is the reads that keep us standing in that booth. Maybe we could even periodically import our border security lists to a local service if we observe a significant network cost in checking against them for each individual scanned through the gate (assuming they are currently maintained remotely by other agencies).

Ignoring the fact that I'm making all sorts of horrible guesses about how this system currently works, these seem like reasonably sensible patterns to me, so what's the rookie trap?

Simply that I didn't start by understanding the basic problem I am trying to solve, instead rolling up my sleeves and diving straight into the technical complexities. In doing so, I might have overlooked a plain, simple solution and that's usually bad - why solve a problem in a complex, expensive way when a simple, cheap way will do just as well?

In this example, the problem is not that 5 seconds is an unacceptable time to process the image, compare the data against the registered users, and then pass all the additional border security checks - the problem is that 5 seconds feels like a long time when you're standing in a glass box waiting for it all to happen!

So what else might we have done instead of a major re-architecture of the iris back end? How about just lengthening the booth to form slightly more of a corridor, with the scanner at one end and the gates at the other? With this simple trick, it still takes 5 seconds before the gates can open, but it doesn't feel like it - you haven't been standing still waiting, there is a sensation of progress.

Same level of system performance, very different user experience.

General engineering lesson 1 - customer experience is king. Monitoring and other data driven metrics are important, but how it really looks and feels to your users matters way more than whatever you can prove with data. They'll judge you by their own experiences of your system, not by your reports.

General engineering lesson 2 - you don't have to solve every problem. Sometimes it's better/cheaper/faster to neutralize or work around the issue instead. You might not be able to build a different floor layout, but you can do things like transfer data in the background (not locking out the UI) and show progress 'holding' pages during long searches etc.

Oh and just for the record, I really have no idea how the back end of the iris system works - you are supposed to be seeing the analogy here...

Thursday, 16 October 2008

What Your Network Guy Knows

So you're getting into distributed systems; maybe you've got some real scalability issues on the horizon, or perhaps you want to better isolate failure, or be able to cope with more concurrent change in the system. So how do you do this webscale thing then?

Time for some homework. Listening to some vendor pitches, maybe reading some books, or getting an expensive consultant or two in for a while (I'll take your money from you if that's what you want) might possibly do it. But before all this gets out of hand, did you realize you're probably sitting right next to a distributed systems fountain of knowledge? You already have someone, right there in your team, who has spent their entire career working with the largest eventually consistent multi-master distributed systems in the world - the trick is they might not even know it themselves - and that someone is your network guy.

Let's test this assertion against a couple of technologies that network engineers deal with every day, and look at what we can take from them into our distributed systems thinking.

How about something fundament - routing protocols. Networking gurus have a small army of acronyms at their disposal here; OSPF, EIGRP, IS-IS, BGP, and the sinister sounding RIP. These are essentially applications that run on network devices (and sometimes hosts themselves), map out the network topology, and provide data for devices to make packet forwarding decisions.

So what can we import from this technology?
1. Partitioning - networks are broken down into manageable chucks (subnetworks) which scope load (broadcasts), ringfence groups of systems for security, and limit traffic across slow and expensive links.
2. Scalability - routing protocols allow massive global networks to be established by summarizing contiguous groups of networks again and again, and ensuring any node can establish end-to-end connectivity without having to understand every single path in the network (just a default route).
3. Failure isolation - subnets are bordered by routing protocols, which form a natural boundary to most forms of network malarky. In the event that a network becomes unpredictable (flapping), some routing protocols are able to mark them down for predetermined time, which aids in local stabilization and prevents issues spilling over into healthy networks.
4. Self healing - when a failure in a network or a link between networks occurs, routing protocols observe the problem (by missing hellos or interfaces going down) and take action to to reestablish reachability (work around the problem using alternate paths etc). Each node will recompute it's understanding of the networks it knows how to reach, learn who it's neighbors are and the networks they can reach, and then return to business as usual via a process called convergence (this is a really simple study in eventual consistency and variable consistency windows).
5. Management - for the most part, networks separate their control messages from the data they transport. A good practice, especially when combined with techniques like QoS, because it significantly reduces the risk of losing control of the infrastructure under exceptional load conditions.

Now let's look at something application layer - DNS. This should be a somewhat more familiar tool (or you're kind of reading the wrong blog) and we touch it quite regularly but probably don't appreciate what goes on in the background. At it's most basic level, DNS is a client/server system for providing a mapping between human-readable hostnames and machine-friendly IP addresses. Oh but it's so much more...

So what can we import from this technology?
1. Partitioning - DNS is hideously, frighteningly big, there are hundreds of thousands of nodes in this system, from the dozen or so root servers all the way down to the corporate internet access edge servers. It is a good example of dividing up a problem; to find us you'd work right to left through a fully qualified domain name, starting with the "." (root), we're in the "com" container (hosted by a registrar), then the "betfair" container (hosted by us), and finally you'd get back some data from a record matching "www" and arrive at our place.
2. Scalability - did I mention DNS is big? DNS uses a classic combination of master/slave nodes and caching on the client and server side to scale out. At the corporate edge, DNS proxies resolve addresses on behalf of internal clients and keep answers in a local cache, ISPs and those who run their own zones keep a number of slaves (many read only) and spread queries out amongst them, and finally an expiry timestamp (TTL) is set on query results permitting client side caching.
3. Resilience - clients can be configured with a list of servers, which they will cycle through should they receive no answer. Additionally, the DNS protocol is stateless, making it easy to move servers around hot and load balance using simple, lightweight algorithms.
4. CAP - DNS definitely prefers availability over consistency, the window for an updated record to be propagated around the internet being ~24hrs in most cases. It's also highly tolerant to network segmentation, individual servers being happy to live separated from the rest of the DNS infrastructure for long periods of time, answering queries, and then catch up with all the changes in the zones they host once connectivity is reestablished.
5. Operations - the hierarchical way the namespace is organized is perfectly matched to how authority is delegated. If you're going to have a massive system spread around the globe, you've got to think about how you're going to operate it, and the DNS model for this is based on allocating administration with ownership. This gives complete flexibility and control to namespace owners without risking the integrity of the system as a whole and let's us operate the biggest distributed system in the world without employing the biggest IT team in the world.

So buy your network guy a coffee. Ask him how his world works. If you can draw the philosophical parallels, it might be the most valuable couple of hours you've spent in ages.

Oh and by the way - distributed systems are all about the network, so you're going to need a friend here anyway...

Thursday, 9 October 2008

IASA Connections - Day 3

Day 1, day 2, and now day 3:

Scott Ambler – Practice Leader in Agile Development, IBM Software Group
• Data modelling from an agile perspective.
• Don’t get too hung up on purist agile, good techniques are good techniques regardless of where they come from.
• Software development is more of a craft or an art than engineering – hence we tend to apply some practices that don’t make things the easiest for us.
• Agile is becoming mainstream – you cannot dodge it – and data is not going to change from being an asset, so how can these things coexist?
• Data and quality are 2 words that are hardly ever seen together, yet this is so important.
• In most “Big Requirements Up Front” projects, 45% of features never used, 19% of features rarely used, so this is effectively a waste of over half the development budget.
• 66% of teams work around internal data groups, most common reasons are difficulty in engagement, responses too slow, and development teams don’t understand the value. So data architects have work to do.
• Modelling is like anything else, it just needs to be good enough for the task at hand (repeatable results, not repeatable processes).
• If you can’t get active stakeholder participation, then cancel the project because all that will happen is disaster
• Clear box testing is just as important as black box testing, because you can test triggers, views, constraints, and referential integrity rather than just observable functionality.
• Do continuous integration of databases – there is nothing special about data so why shouldn’t it be treated the same?
• Make it easy for people to do the right thing – loads of verbose documentation and white papers are less likely to be effective than a small number of run-able assets and some 1:1 support to integrate them.

What I think
• Obviously Scott was wearing his data hat this time, but clearly the whole session was predicated upon the fact that you believe relational databases are themselves the right solution…
• Really like the “repeatable results not repeatable processes” phrase, it is such a powerful idea – I am always battling the ‘1 process to rule them all’ crowd.
• Probably best whiteboard walkthrough of the “karate school” example I’ve ever seen.
• My approach to modelling has always been to define things in order of ‘most difficult to change later’ to ‘least difficult to change later’ so when you run out of steam the unknowns you’re left with are the cheapest ones.
• Abstractions – a lot of the examples in the talk were based around the assumption that applications directly accessed data, we need to think more about how we can build systems that don’t need to know details about schemas etc (access via object etc).
• Totally agree with the active stakeholder participation thing, if it’s important enough for them to expect you to deliver it then its important enough for them to invest themselves in it.

Dr Neil Roodyn - independent consultant, trainer and author
• A session titled “software architecture for real time systems” was about patterns for performance and performance tuning.
• Hard vs. soft real-time distinctions important.
• Time is so often not considered in system design – we think about features and quality and failure but so little about latency.
• Automated failure recovery is so much more important in real time computing because you cannot stop to allow human intervention upon failure.
• There are some strong similarities between real time computing thinking and distributed systems thinking:
1. Consistency
2. Initialisation
3. Processor communication
4. Load distribution
5. Resource allocation
• Asynchronous is kind of “cheating” as it leads to the illusion actions have completed before responses are returned.
• The 3 most important considerations in real time computing are time, time, and time (haha very good Neil).
• Common software tricks and patterns for real time systems (obviously assuming real time performance is your overriding requirement):
1. Use lookup tables for decision making
2. Used fixed size arrays
3. Avoid dynamic memory allocation
4. Reduce number of tasks in the system
5. Avoid multithreaded design
6. Only optimise popular scenarios
7. Search can be more efficient than hash
8. Use state machines
9. Timestamps instead of timers
10. Avoid hooks for future enhancements
11. Avoid bit packed variable length messages
12. Reduce message handshakes
13. Avoid mixed platform support
14. Minimise configurable parameters
• Overall know your system and approach performance tuning scientifically, observe where time is lost and spend energy there, don’t just guess.

What I think
• When we think about SLAs for latency we have to make sure we consider time from the users perspective – if you have a very fast back end but it takes ages for results to render for users, then is it really high performance?
• Even if you have a few processes in your system that need to be real-time, chances are the majority of your system does not, so don’t be afraid to mix memes because if you make the whole thing real time end-to-end you might be unnecessarily sacrificing some scalability or maintainability.
• Totally agree with points on developers needing to know more about the tin their systems run on and how this will lead to better software overall.
• I cant’ help but think we’re getting lazy from our (relative) lack of constraints – back when you had 32K to play with you really thought hard about how you used that memory, when you had to load everything from tape you really planned that storage hit…

Neal Ford – Software Architect and Meme Wrangler, Thoughtworks
• Fairly by-the-book session on “SOA won’t save the world” but via the humorous and engaging analogy of Chuck Norris facts.
• “Peripherally technical manager” types are the key causes for SOA overpromising.
• Good definition of a service as a unit of course grained, self-contained business functionality.
• The tension will always be on between centralised planning and tactical action, so you need to learn how to plan ahead without the planning becoming a constraint on business agility.
• Beware of “cleaning up” the messy communications paths in the enterprise by hiding them inside a box (ESB) – you still have same underlying problems, but you suddenly have less visibility of them.
• Beware of the difference between ‘standards based’ and ‘standardised’ i.e. most vendor ESB solutions share some common basic standard foundations but the functionality has been extended in a proprietary way – so it can still mean lock in.
• Keep track of the number of exceptions you’re granting against the governance you have in place – too many and you might have excessive governance.
• Using ubiquitous language is a must; perhaps even have a formal dictionary for each project.
• The business must be in integration projects not just initiate them.
• We all like a bit of ESB-bashing but they can still be useful for connecting up things like mainframes and 3rd party systems to your nifty REST/WS fabric.
• Exchanging metadata is a great way to negative communication parameters (reliability, security, synchronicity etc) between services and consumers.
• SOA is undebugable – but it is testable - so a good testing discipline is essential.

What I think
• The insurance industry is the place I’ve worked with the most legacy out there (you cant retire certain mainframe systems until all the policyholders die!) and the ESB attachment is just the right milk for this cookie.
• We as engineers contributed to the overselling as much as the Neal’s peripherally technical manager did – I think we got carried away with the interest that a bit of technology was suddenly getting and we were happy to be on the bandwagon as we usually struggle so hard to get technical things on the agenda – how could we not ride this wave?
• There are more benefits to SOA than reuse yet that’s all we ever seem to talk about. How about what it can do for scalability? Failure isolation? Concurrent change? Hot maintenance?
• Yes. BPEL. Terrifying.

The Big Summary
Overall I think this was a very good flagship event, my thanks to the organisers. The turnout was a good size – small enough to feel personal and allow plenty of networking opportunities, yet big enough to ensure a variety of engaging discussions.

The IASA mission is a worthwhile one, and one that I think we don’t do enough about in any technology discipline. Whether we’re talking about architects, system administrators or developers, how much time do we spend investing in our community? In ourselves as a profession? When was the last time you looked for someone to mentor? Went out of your way to share your ideas beyond your organisational boundaries? Visited a university to see what the talent you’ll have to work with in 5 years is actually learning? Investing in ourselves as an industry is undervalued, and I’m happy to be part of a group trying to address this.

If there is 1 thing I would change for next year, it would be the format of the talks. There are already enough conferences you can go to and watch someone meander through a slide deck (this was great meandering though!). If we change the focus so that speakers only use 50% of the allotted time and treat their role as setting the scene, then we could use the other 50% to get a real group discussion going on the topic at hand. I would certainly find that more valuable, and I would suggest that promoting high intensity peer discussions on tough technology and strategy issues would probably better serve the mission of establishing architecture as a profession.

I have been assured that you will eventually be able to find the slides from the formal sessions and keynotes here.

So that was IASA Connections. Tomorrow I’m off to UC Berkeley for the day, so probably best ease back on the beer this evening (it makes it harder to maintain the illusion of cleverness I’ll need). Sayonara.

Wednesday, 8 October 2008

IASA Connections - Day 2

Ceteris paribus, what comes after day 1 of a conference? Well, day 2 of course…

David Platt - teacher and author (and mad professor?), Rolling Thunder Computing
• Day 2’s keynote on why software sucks, which was adapted from his book by the same name.
• Lots of statistics on why users hate our software, mostly boiling down to the theory that software is built by geeks for geeks but actually used by regular folks.
• 2 million web users in 1994 has become 1200 million in 2006; and almost all are now laymen (in 1994 almost all were geeks themselves).
• Platt’s rule, “know thy user for he is not thee”
• Users don’t want to use your application, they want to have used it – so understanding that you provide a means to an end rather than an end in itself is a helpful thought pattern.
• Customers don’t buy software, they buy the outcome it’s intended to create, e.g. you don’t buy a drill from B&Q, you are really buying a hole.
• Transferring extra clicks into cash (salary costs of time spent clicking) is a useful way to demonstrate this to management.
• Suggested solutions:
1. Add a virgin to your design team, i.e. get someone never used your system before to try it and observe their challenges.
2. Break convention when needed – for example, why have a save button if you could just have the system save things as you go?
3. Don’t allow edge cases to reach mainstream – if something is really unlikely to be used by more than 1% of visitors, why include it in the main real estate?
4. Instrument carefully – watch user experience, track clicks, see what users actually click and how frequently, how do they arrive at certain pages/features?
5. Always question each design decision, “is it taking us closer to ‘just working’ or further away?”

What I think
• Some of the talk didn’t apply to Betfair per se, as online gaming/gambling etc joins the ranks of things like porn (can I say that?) in software that’s used for the experience, rather than to go through a process to arrive at a destination.
• Most of the examples are based on software that shipped with pointless features or usability issues. What wasn’t addressed was how architects and engineers relate to this – I agree that you can make terrible usability errors, but this is usually a decision making process by product managers and other stakeholders rather than the result of developers work. More material on how engineers can push back on these decisions would help us as a profession.
• Instrument carefully is good advice, and in my opinion is critical to effective A/B testing. Knowing what your customers like best coupled with the ability to try new layouts or versions in a lightweight way is a pretty important to keeping the best software out there.

Ted Neward - independent software development architect and mentor, Neward & Associates
• What are architects really about and what does architecture mean?
• We tend to get carried away with “what if’s” like what if I want to change logging system later so build in 96 logging APIs and pretty much use 1 or 2.
• Do we have architectural styles in the same way as building architecture has styles?
• Defining pragmatism – avoiding idealism in favor of something appropriate.
• There is no such thing as NFR, they are all just requirements.
• What do architects do:
1. Understand (what’s the problem, what’s the constraints)
2. Reassess (changing goals, changing constraints)
3. Explore (more potential solutions, new opportunities)
• Beware of the coolness trap – cool technology doesn’t mean appropriate technology.
• The 3 kinds of architects:
1. Infrastructure – datacenters, networks, storage
2. Enterprise – CTO high level leadership
3. Solutions– the “per project” answers to business questions
• Patterns are not architecture; they are simply a vocabulary we can use to have high-speed discussions about technical ideas.
• When designing systems, make big decisions first, then next most detailed, then next most detailed…
• Idea of architecture catalogue (the things you do as an architect)
1. Communication – transports, exchanges, and formats.
2. Presentation – UI, style, and delivery.
3. State management – durable vs. transient, context vs. process.
4. Processing – implementation, transactions, and shared data.
5. Resource management – location, registry, discovery.
6. Tools – languages, data formats.
• If you don’t explicitly define architecture it will be implicitly defined for you!
• Architecture is a bigger picture view than a developer would typically take.

What I think
• Not sure I agree with the bigger picture assertion, as I think this promotes the ivory tower perception of architects – and besides, successful software demands that everyone involved in building it understands the bigger picture.
• You need to consider future options, but take into account likelihood and difficulty to change and watch for entering diminishing returns!
• One of the reasons traditional architects don’t suffer the same difficulties we do is that the constraints and practicalities in real world construction are so much more visible. We need to put more effort into making these understood.
• I like the NFR idea because so few people talk about scalability and availability etc as business benefits, but they most certainly are!
• Agree with the patterns point, too many people get hung up on them but they do not describe a working solution.
• While I always like to talk about defining architecture as a trade, I am not sure about the catalogue idea – some of those decisions (like presentation, data formats, and languages) and surely best made by those closest to the problem; i.e. the delivery engineers.

Dr Neil Roodyn - independent consultant, trainer and author
• Gave a talk called “it’s all wrong, change it all” a rather provocative title that attracted me to the session…
• We know things are going to change, so how can we put ourselves in a position where this is as easy as possible?
• We’re in a change heavy industry, however, humans are naturally change averse so this is something we have to work hard at.
• Abstractions actually make it harder to change things, because they bind code to a particular abstraction – and people tend to feel emotional attachment to their implementations!
• Big visions are so important - always remember that’s what you’re delivering against, not the details.
• We get carried away with reusability – make sure the expected demand for it to be reusable justifies the cost of building it in a reusable way.
• How you design your system can make it more change-friendly or less change-friendly, this is how architecture can help.
• People are the biggest factor – there is a fine line between continuous improvement and gold plating.
• Don’t underestimate malleability of code.

What I think
• People typically associate change with risk or loss. Part of the trick to getting buy in to ideas and making people happy to adopt changes is to address good-old-fashioned “what’s in it for me?”
• Abstraction layers scares me because we’re not getting smarter at the same rate that we’re abstracting away from the primitives. I think we have a problem as an industry, which is convincing people to learn to be engineers (computer scientists) over quick and dirty coders (learn Java in 28 days and get a job).

Paul Preiss – President, IASA
• Dealing with how we establish architecture as a profession in it’s own right.
• To be a profession something must have:
1. An identifiable body of knowledge
2. Able to enter this trade without having to have been something else first
• Helping to realize architecture as a profession is a key purpose of the IASA group.
• America Institute of Architects formed in 1857 because (sound familiar?):
1. It is difficult to solve real architecture problems due to lack of targeted resources
2. It is difficult to find experienced architects
3. It is difficult to be of maximum value to our employers due to lack of stable job definition
4. It is difficult to tell a qualifies architect from an unqualified one
• Architects tend to be in one of 4 major groups:
1. Corporate
2. Vendors
3. Thought leaders
4. Service integrations
• Professional perspectives and skills taxonomy are resources we’re trying to build up – providing that ‘identifiable body of knowledge’
• The skills one must master to truly deserve the title of architect are:
1. The IT environment
2. Business technology strategy
3. Design
4. Human dynamics
5. Quality attributes
6. Software architecture
7. Infrastructure architecture

What I think
• Working towards formalizing architecture as a practice, a role, and a valuable and necessary part of a team is a massive undertaking – we have work to do here as an industry.
• Perhaps the key to this is working backwards from result? Maybe we need to ask ourselves “how do we test for architecture?” If we can work out what we’d be able to observe in an organization with this nebulous architecture thing in it vs. one that does not, then we’ll have an answer and some benefits to point at!
• In the short term we can’t test for architecture so how do we find them? Well you can test for thinking patterns, values, and philosophies so look for the ones that contribute the most to your organizations definition of success.
• Perhaps we need a charter? Some publically visible set of principles that anyone engaging a software architect should expect to be met?
• Good to see the ‘ities’ discussed as central to what we do.
• I still say it’s science Mr. Preiss – but pragmatic science! We solve real-world business problems by using our skill and experience to apply the right technology.

And with that I must once again apply my problem solving skills to the problem of unconsumed beer. See you tomorrow, same bat-time, same bat-channel...

Tuesday, 7 October 2008

IASA Connections - Day 1

This week I skipped across the Atlantic to attend the International Association of Software Architects & Architect Connections conference in San Francisco. Between my failed attempts at getting a chapter off the ground in Romania and being a long-standing member of the London chapter, IASA has been a hugely valuable organization to be associated with. There are regular activities at most major IT hubs in the world, with a strong focus on sharing ideas and meeting other people with similar technology challenges.

For the next 3 days I have a fairly hefty schedule of people to meet and sessions to attend - so I'll try and throw up a brief summary post at the end of each day covering what's discussed. So let's dive straight into day 1:

David Chappell - serial technology writer and speaker, Chappell & Associates
• Gave the first days keynote on cloud computing, covered the basics (this is still a very misunderstood topic) and direction over the next few years.
• Cloud computing falls into 3 main categories; cloud delivered products like windows live, attached services such as spam filtering and email antivirus, and cloud platforms like EC2 and S3.
• There will always be a mix of 'onsite' software and cloud based services in every organization in the future - so clouds will not rules the world!
• Advantages of cloud computing include lower costs and less financial risk (as capacity grows with demand, rather than having to build for peak from day 1).
• Disadvantages of cloud computing include trust issues, data protection, and regulatory requirements.
• Important to distinguish between consumer (free and ad supported and usually less reliable) and business (usually paid directly and covered by an SLA) cloud solutions.
• Underlying message is really about change and how hard it is - and how this relates to making the paradigm shift we need to get the enterprise to accept cloud as a valid technology.

What I think
• The cynical side of me can’t help but think we’re throwing things we've been doing for ages (like hosted email virus and spam checking) into the cloud bucket now that we came up with a new word for it.
• I consider some of the constraints of building on a cloud platform to actually be benefits – forcing developers to abstract away from hardware means you’re building systems that are inherently more scalable, available, and hot maintainable (whether deployed in a cloud or onsite).
• Lack of enterprise strength SLAs are keeping a lot of organizations away from cloud computing. Perhaps we as engineers have an obligation to help the business start to look less at SLA and more at actual performance? Most of the time a cloud infrastructure will trash a fixed internal hardware deployment in overall availability yet he SLAs don’t yet demonstrate this.
• Cost is very much still a factor when moving to a cloud deployment, but you move to a marginal cost consideration – you don’t want to run an expensive piece of code for each hit, since that unnecessarily increases the cost of the hosting. In a traditional model it doesn’t matter so much if you have expensive code running most of the time if you’re using capacity normally idle except during peak – now that costs you every time you execute it.

Dr Neil Roodyn - independent consultant, trainer and author (and big fan of XP)
• The “capital A” Architect vs. the idea of “little a” architecture, talking about what the role really should be and how it works in agile.
• In software we sometimes borrow a little to heavily from industrial engineering.
• Architecture is a practice created to try and put predictability back into a process that is inherently unpredictable (software delivery).
• Traditionally we try to separate design from construction – i.e. have really smart architects design the system and then any idiots can code it – and how this is flawed thinking.
• Change is inevitable in software projects, most of our traditional processes require rigid and stable requirements in order to be successful but this is not real life.
• Do the best developers only end up architects because we romanticize the role too much? Or it is the only way they see they can get career progression? Wouldn’t we rather have the best coders coding?
• Maybe we need to start looking at developers more as craftsmen and less like engineers?
• Be careful how you incentivize people, because that’s what you’ll get!

What I think
• Something omitted here is that the quality of an engineering team’s output can never exceed the quality of it’s input, so there is a strong dependency on working well together with customers to truly understand requirements and make the right tradeoffs.
• Incentive is a very valid point, if you measure architects on creating verbose design documents or UML diagrams then that’s what you’ll get – try measuring them on quality, working software.
• The people that know how best to solve problems are the people closest to their effects, so architecture has to be about harnessing the individual developers skill, experience, and exposure to the domain – not trying to tell them what to do.
• I quite like the label “engineer” because it stands for solving real world problems with technology – but I do agree the process does need to be considered to be more creative than it currently is. I recently read something that likened software development to film making, which I think is a powerful analogy.
• Why does IT have such a bad reputation? I don’t think it is as simple as failed projects, I think it is how they’re ‘washed up’ afterwards too. Working closer with customers along the way makes sure they’re aware of the impact of their decisions (changing/adding requirements) so you can easily end up with projects over time/budget, which are not considered failures by the business – because they expected it and were involved along the way.

Randy Shoup - Distinguished Architect, eBay
• The architectural forces governing eBay are scalability, availability, latency, manageability, and cost.
• Their architectural strategies are partition everything, asynchronous everywhere, automate everything, and remember that everything fails!
• Data partitioning is dividing DBs by functional areas (user, items, feedback) then sharding so that each logical DB is horizontally partitioned (by a key such as itemID) which provides scalability for write heavy data sets.
• CAP - their system prefers availability and network partition tolerance and thus trades away consistency. Variable window for different features.
• Functional segmentation at application server layer follows the same pattern as the databases (selling, search, checkout).
• Most operations are stateless which means the most basic, off the shelf load balancers can be used to horizontally scale application server tier.
• When travelling though the system, what state is generated is accumulated in cookies, URLs, and a scratch (periodically flushed) DB.
• Patterns used:
1. Event dispatch (new item listed, item sold)
2. Periodic batch (auction close process, import 3rd party data)
3. Adaptive configuration (dynamically adjust consumer thread pools and polling frequency based on SLAs)
4. Machine learning (dynamically adapt experience by collecting data for the day on for example recommendations and then try different ones next day)
5. Failure detection (collect data on activity send on multicast message bus and listeners watch for certain error messages)
6. Rollback (entire site redeployed every 2 weeks and no changes cannot be undone, features rolled out in dependency tree order)
7. Graceful degradation (switch off non essentials, defer processing to more guaranteed async messages)
• Message reliability dealt with via framework.
• Code deployment decoupled from feature deployment, so new versions can be rolled out with dormant functionality (they call this wired off) that can then be turned on gradually.
• NOT agile and don’t claim to be!
• Completely redeploy entire site every 2 weeks – although this is more of a constant, rolling upgrade than the big bang it sounds like.

What I think
• A very agreeable talk, particularly around deployment, versioning, and A/B testing.
• The architectural forces are very similar to our 6 principles (availability, scalability, maintainability, quality, security, and user experience) and really are just different words to describe the same good practices needed to meet the challenges we have in common.
• State is the enemy of scalability, and it is refreshing to see someone tackling this well - instead of saying "how can we build a distributed state tracking system this big?" they're saying "how can we build our system so that the functionality does not depend upon a central state system?"

Rob Daigneau - Chief Architect, SynXis
• Anti-patterns - human behavior in software projects and how to deal with it.
• Overdependence on methodology as solution to all problems and smooth project execution – not enough focus on personalities and simple human nature.
• Individual anti-patterns:
1. Cyber addict – using only IM or email etc for communication is very efficient, but not necessarily effective as you can lose the meaning of your message.
2. Fortress – not sharing knowledge and being secretive leads to good old fashioned unsustainable codebases and key man dependencies.
3. Ugly baby – too little care taken with how and when criticism is issues can lead to valid advice and points being ignored to the detriment of the project.
4. Perfectionist – believing that masterpieces are the only way every time can lead to unnecessary gold plating, artificially inflating the cost and time to market beyond what’s beneficial to the organization.
5. Conquistador – being overzealous about "the one way to do it" can mean failure to make good tradeoffs.
6. Workaholic – not having the right work/life balance will only lead to burn out and mistakes made.
• Team anti-patterns:
1. Hazing – throwing people into the deep end with very little coaching or attention to integrating with the existing team often means they take a long time to become productive.
2. Fight club – the organization can become a casualty in pointless battles between architects and developers, developers and testers etc unless teams learn to work together.
3. Wishful thinking – working out some estimates that show a certain milestone cant be reached in a certain timeline means just that, no matter how much you’d like it not to.
4. Firing squad – if people are scared to disagree or the culture doesn’t encourage the introduction of new ideas; the organization can be robbed of great value that stays locked away in engineers’ heads.
5. Too many cooks – if there are no clear boundaries then consensus becomes a huge issue and teams become paralyzed, unable to make progress because of endless circular discussions.
• Leadership anti-patterns:
1. Deer in headlights – if a leader wont (cant?) make a decision then the company stands still and competitors gain ground.
2. Cliff jumpers – taking risks for the sake of risks or making decisions on dangerously incomplete data can waste time, money and patience.
3. Spin zone - talking talk not walking walk gets transparent pretty quick.
4. Drill sergeant – exercising authority in an aggressive way makes very short-term gains and never gets a team behind a goal.
5. False summits - artificial deadlines or objectives can be dangerous, if the activity doesn’t turn out to be committed to, a loss of morale and trust in management can result.

What I think
• Reasonably fundamental stuff for experienced management but good to see it getting airtime in this crowd, architects typically come up via technical tracks and probably don’t spend enough time on their influencing and consensus building skills given how important a part of the role this it.
• This would have been a good opportunity to talk more about incentive and how it drives behavior. A lot of anti-patterns can be traced back to KPIs that encourage/reward the wrong things.
• Preventing burnout and keeping sustainable development going are some key reasons I like SCRUM – working in sprints gives you a cyclic mix of high intensity work interspersed by more passive, thoughtful phases.
• I liked the Gerald Weinberg quite "no matter how it looks at first it is always a people problem".

Ken Spencer – Practice Manager, Solid Quality Mentors
How agile applies to traditional, formal technical projects using a current project for the US government as a case study.
Manufacturing background so most examples look back to this experience.
Looking at why most projects fail – this is because people fundamentally keep doing what they do.
Given that we almost automatically repeat what we know, the good news is that this means being successful once significantly increases the likelihood of being successful again.
Spend commensurate amount of time planning - you need plans but you need to know when to just start work and learn from doing.
Good enough – what are the testing criteria and when are you into diminishing returns?
The ‘love curve’ which is a cycle you go through when taking over a failed project; initially distrusted though bad experience, then looked upon as savior, then reality sets in, then they see sustainable success.
Getting back to basics – when things go off the rails look first at the simplest units of work the team ought to be doing and this is usually where you will find your answers.

What I think
• Largely based on the agile manifesto, so we have a pretty strong philosophical connection here.
• Slightly damming of waterfall, at the end of the day it isn’t all bad and isn’t evil, I think it’s quite suitable for very repeatable, commodity projects as long-horizon predictability is possible and the phase space of all possible features is finite.
• Not sure I like the label ‘formalized’ when used to describe waterfall vs. agile, as this kind of indicates less control, visibility, and organization around agile when in fact I think these are some of its strengths.

Whew! Time for beer now, see you tomorrow…